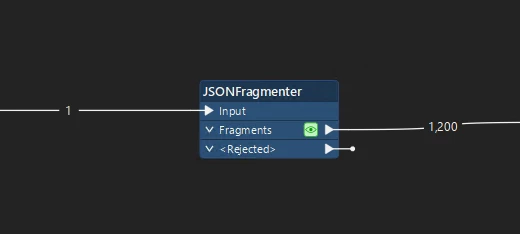
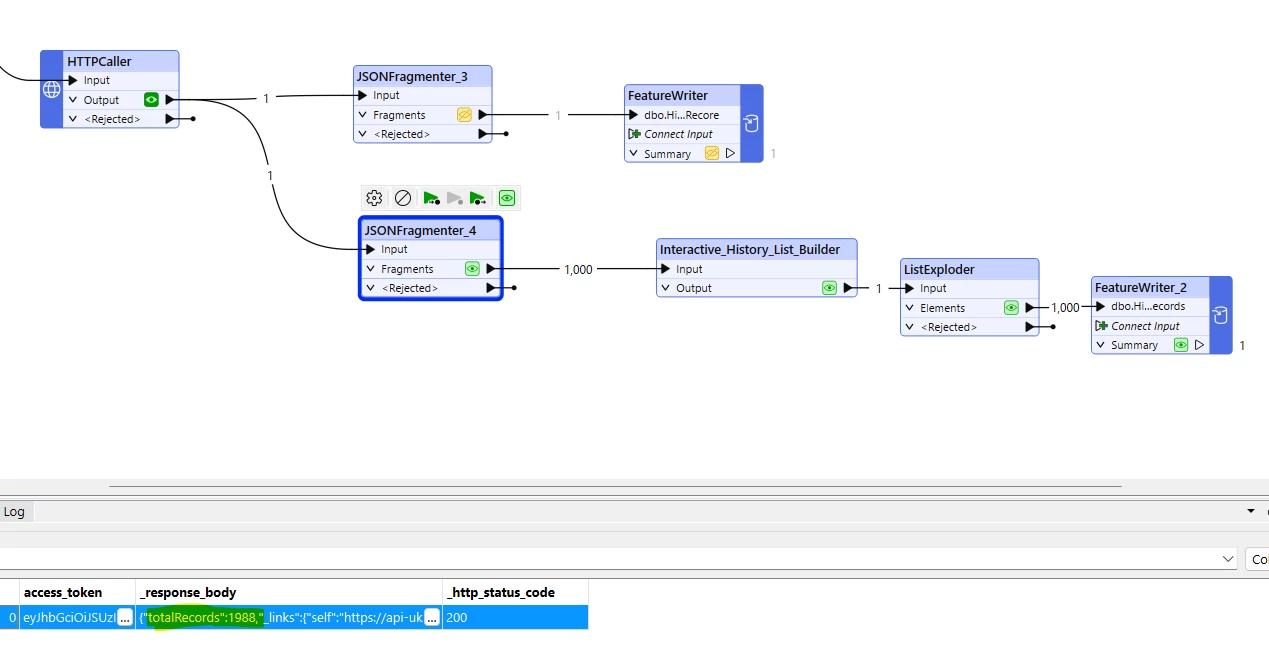
Could it be that your endpoint is paging the results in groups of 1000? The tag “totalRecords” leads me to believe that you might be dealing with paging here.
Open the _response_body in your editor of choice and count the number of elements in the raw data. Also look for a URL for the second page, in particular in the “_links” tag.
That looks to me that there are 1988 records to return total, but it’s typical that only 1000 are returned in a call and it’s necessary to make multiple calls with pagination to return all records.
Since the API provides the total number of records fulfilling the query in the response, you could extract this with a JSONExtractor, then use a Cloner to create a feature for each of the offset queries needed to return the entire amount of records. Send these through a second HTTPCaller. So the first feature through that HTTPCaller would request records 1-1000, while second would request records 1001-2000. This is more efficient than looping, since you can set the HTTPCaller to use concurrent requests to minimize the waiting time.
I am attaching an example illustrating how to do this that requests album information from Spotify, with 20 records per page.

 +1