I need to extract the Hex Code Point of multiple letters using TextEncoder.
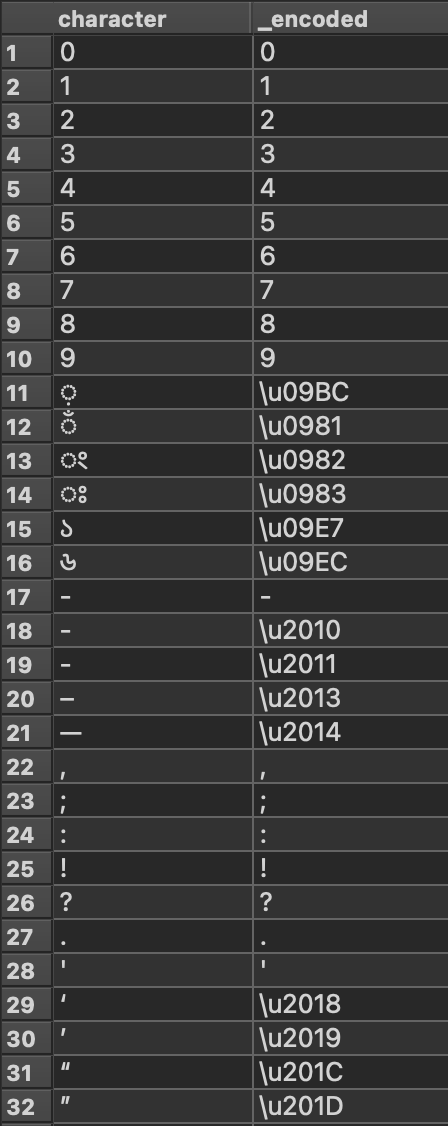
However, the transformer fails to encode Roman numbers and some special characters. You can see in the below screenshot that it successfully encodes Bengali letters and some special characters, but not the others.
Anyone has an idea how to solve it or any workarounds? Thanks!
Best answer by david_r
From the documentation, under the "Unicode" heading: All characters with standard ASCII representations are not encoded. In this context, it seems to indicate 7-bit ASCII.
If you want to encode these characters, you can encode them to HEX and optionally prefix the result with "\\u00" to get the corresponding Unicode code point.
This post is closed to further activity.
It may be an old question, an answered question, an implemented idea, or a notification-only post.
Please check post dates before relying on any information in a question or answer.
For follow-up or related questions, please post a new question or idea.
If there is a genuine update to be made, please contact us and request that the post is reopened.
From the documentation, under the "Unicode" heading: All characters with standard ASCII representations are not encoded. In this context, it seems to indicate 7-bit ASCII.
If you want to encode these characters, you can encode them to HEX and optionally prefix the result with "\\u00" to get the corresponding Unicode code point.